You've done this in a shop. The top model has the best reviews and the biggest price tag, and you stand there wondering whether "best" is worth paying double for.
Claude Fable 5.2 is that top model. The price tag is bigger than double.
Anthropic released it on 9 November, the newest arrival in a crowded few weeks of launches. In the data we pulled on 14 November, it sits top of Epoch AI's capability index, which rolls lots of standard tests into one score.
Fable 5.2 scores 173. Google DeepMind's Gemini 4 Carbon is second at 170.
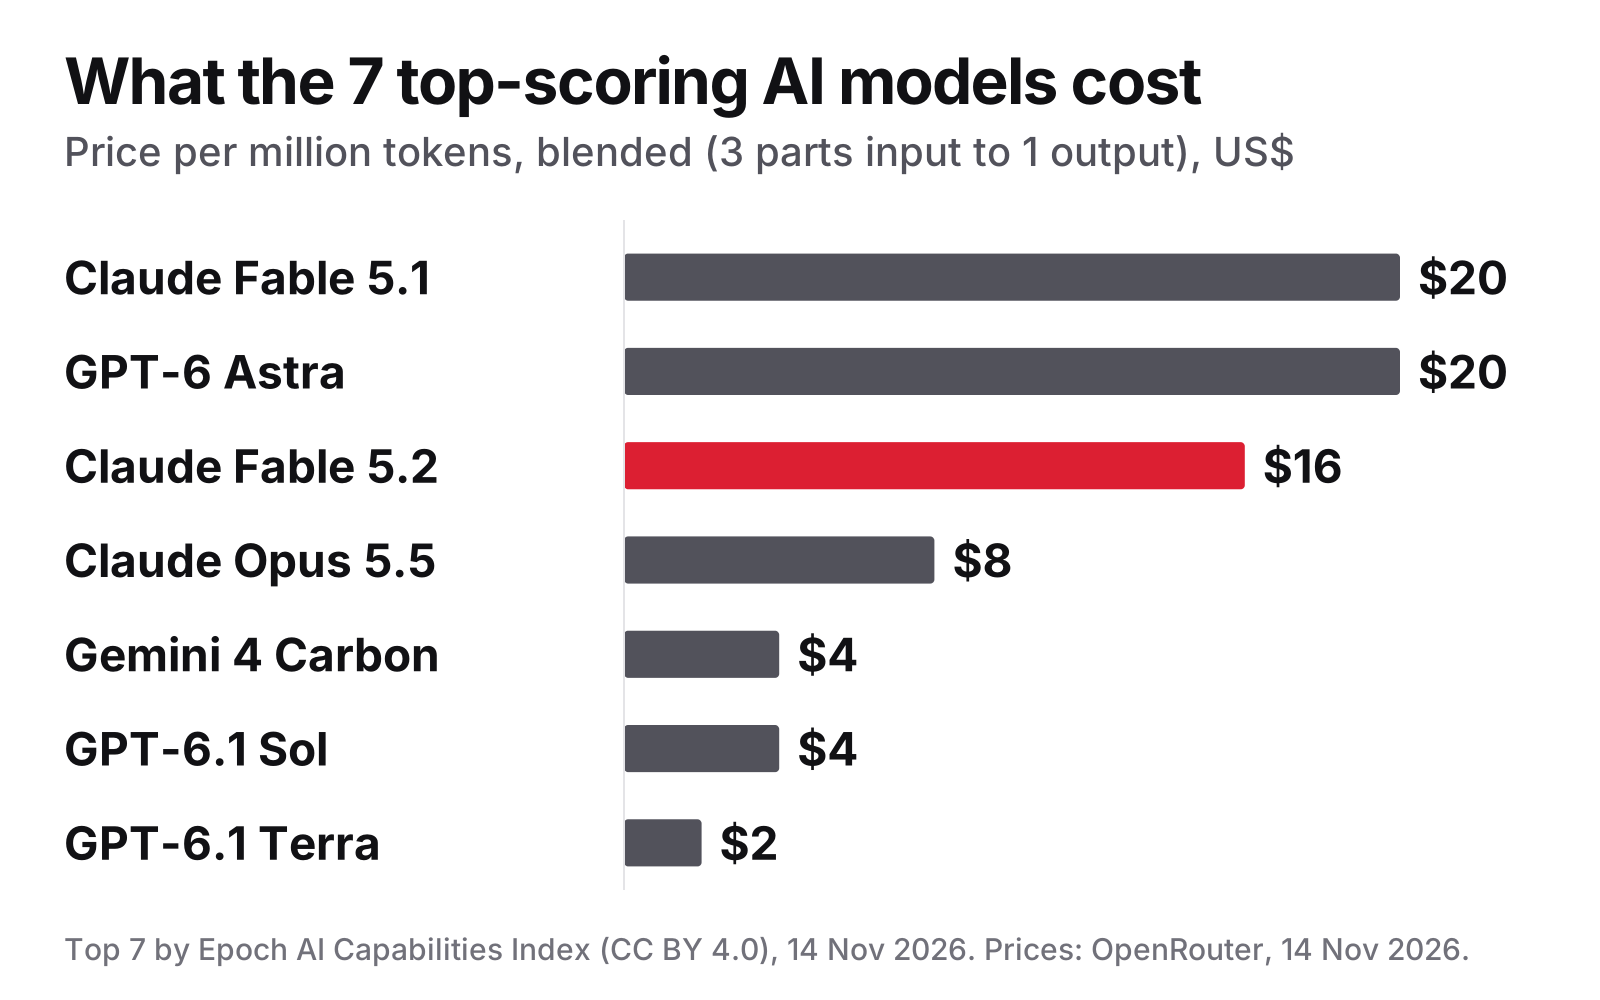
Now the bill. On OpenRouter's listed prices, Fable 5.2 costs $16 per million tokens, the units AI text is billed in. Gemini 4 Carbon costs $4. Four times as much. (Both blend the price of text in and text out, as our /compare page does.)
These are API prices: what companies pay to plug a model into their own apps. They have nothing to do with a chat app's monthly subscription.
So is first place worth four times the money? Mostly no, and the reasons are more interesting than "it's expensive."
The lead is smaller than it looks
The top seven models are a photo finish (here's why), so Fable 5.2 is the favourite for No. 1, not a proven No. 1.
Now shop it like a shopper. For what one Fable 5.2 reply costs, you could get four from Carbon or OpenAI's GPT-6.1 Sol, or eight from GPT-6.1 Terra, assuming each writes the same amount. Terra is in that photo finish too. It costs an eighth as much.
That assumption matters. Price per token is not price per answer. Google says Carbon spends more tokens than its sibling Gemini 4 Argon, exploring and double-checking its work. A wordy model claws back some of its discount, and we have no figures on how much each one writes. Treat these multiples as a rough guide, not a receipt.
The "four times" has an expiry date
This one cuts in Fable's favour. Carbon's price is introductory. Google's launch post says it ends on 30 November, after which Carbon's prices double. Fable 5.2 would then cost twice the runner-up, not four times.
Still double. But if you're building something meant to last past this month, plan around "twice."
And Fable 5.2 is cheaper than its predecessor. Fable 5.1 costs $20, the same as OpenAI's GPT-6 Astra, and both score lower. If you pay for either today, Fable 5.2 scores higher for 20% less. An upgrade that's also a discount is rare.
Where the extra money buys something
The strongest case for Fable 5.2 is maths. On FrontierMath, Epoch's very hard maths test, it scores 95%, first of every model tested. GPT-6 Astra and GPT-6.1 Sol tie for second on 94%.
A lead at the top of a test that hard counts for something. It's also less than two points, and GPT-6.1 Sol gets that close for a quarter of the price.
Science is less flattering. On GPQA Diamond, a set of tough science questions, Fable 5.2 ties for 17th. Carbon is first. Claude Sonnet 5.5, at a quarter of Fable's price, beats it too.
Then there's what we can't see. Epoch's coding results in this snapshot don't include Fable 5.2 or any of the top seven, so no coding verdict. It has no score yet on LMArena's public voting leaderboard. And there's no independent speed data. Anthropic says its new models write up to 30% faster than Fable 5.1. That's Anthropic's claim, and "up to" is carrying a lot of it.
So who should pay?
Anthropic is fairly candid. Its launch post says its Fable and Mythos models are best for "the most ambitious, open-ended technical work," and recommends starting with Claude Opus 5.5 for most coding and knowledge tasks. Opus 5.5 is half the price. I'd take the hint.
Pay for Fable 5.2 if your work is hard maths or research-level technical problems, where a better answer is worth far more than the bill. Or if you're on Fable 5.1 or GPT-6 Astra now, because switching is a straight price cut.
Skip it if you're a student, building a side project, running a chatbot, or doing anything at volume. GPT-6.1 Terra sits in the same photo finish for an eighth of the price, and Opus 5.5 does the same for half if you'd rather stay with Anthropic.
Never paid an AI bill? This still reaches you. The AI features in your apps are built by someone weighing exactly this trade-off. My guess: most will land on a cheaper model from that top seven, and that's not a downgrade worth worrying about.
"Smartest model" is a contested title this week. "Best value near the top" isn't.


